The Architect's Own Use of AI: Drafting, Research and Review in Modes 1 to 3
Chapter 12 belongs to Part III: The Architect's AI Team. It starts with the architect as a user of AI before it turns to the agents the architect designs. Every security architect now has access to assistants that draft decision records, summarise standards, review a design against a catalogue and read a configuration faster than a person can. This chapter describes what the architect can usefully do with them, what the evidence says about speed and quality, how architecture information stays confidential when it describes the organisation's own defences, and which records make the use reviewable. It concerns Shift 1, from documents to code, because the architect's drafts are artefacts in a repository that tests and reviewers can check, and Shift 4, from sole author to conductor of an AI team, because the first step towards conducting a team is to answer for the output of one assistant.
The chapter treats Modes 1 to 3 of the series' usage modes: Mode 1 Conversational assistants, Mode 2 Embedded workplace assistants and Mode 3 Agentic work tools (AI Governance, Chapter 2; AI Platform and Security, Chapter 2) (168, Nordqvist, 2026) (169, Nordqvist, 2026). In these modes the AI acts with the architect's identity and the architect answers for everything it produces. This book builds on the conclusion that the usage mode, not the model, sets the risk, and that an AI acting with a person's identity differs in kind from a Mode 5 agent with an identity of its own (AI Red Team, Chapter 6) (170, Nordqvist, 2026). The agent team with identities of its own is the subject of Chapter 13; the question of how to review what any of them proposes is the subject of Chapter 14; keeping the craft alive is the subject of Chapter 15.
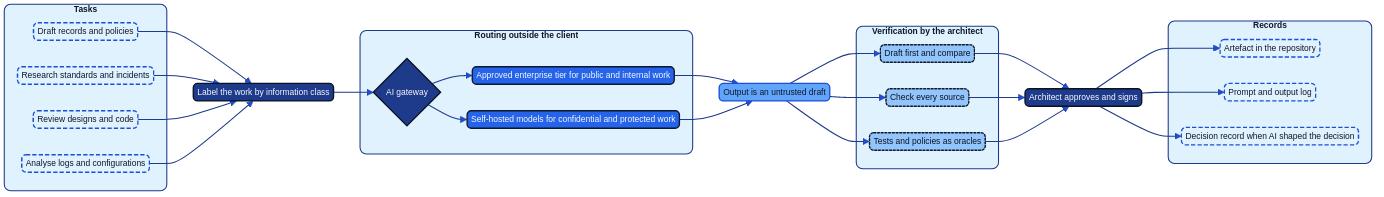
Figure 12.1: The architect's own AI work in Modes 1 to 3: tasks, routing by classification to approved or self-hosted models, outputs, verification and records.
What architects use AI for
The architect's work divides into four kinds of task where an assistant can take part: drafting, research, review and analysis. Each has a different failure mode, and the verification that suits one does not suit the others.
Drafting covers decision records, policy text, threat-model narratives, tender security annexes, board papers and the prose around control catalogue entries. An assistant produces a competent first version quickly. The failure mode is a fluent draft that states a position the architect never reached, or omits the alternative that mattered.
Research covers reading standards, regulatory texts, vendor documentation and incident reports, and answering questions such as which article of an instrument imposes a duty. The failure mode is fabricated or misattributed sources and confident summaries of documents the model did not read. Package and library names are a documented instance: a study of code-generating models found that they recommend packages that do not exist, and that the rate differed between commercial and open-weight models, higher for the latter (197, Spracklen et al., 2025). An architect who researches with an open-weight model on self-hosted capacity, as Nordvik Region does below, must therefore verify more, not less.
Review covers reading a design, a pull request, an infrastructure definition or a policy against a standard or the control catalogue (Chapter 9) and listing the gaps. The failure mode is the plausible gap that does not exist and, more dangerous, the real gap the review did not mention.
Analysis covers reading logs, configurations, firewall rule sets and exported policy to find patterns: which service accounts hold broad roles, which egress rules are unused, which exceptions have expired. The failure mode is an invented pattern, or a correct one reached on a sample the model happened to see.
| Task | Typical use | Characteristic failure | Verification that suits it |
|---|---|---|---|
| Drafting | First version of a decision record, policy or annex | Fluent text that states an unreached position | Architect writes the position first; compare |
| Research | Locating the article, standard or incident report | Fabricated or misattributed source | Open every cited source and read the passage |
| Review | Listing gaps in a design or pull request | Invented finding; missed finding | Own review first; tests and policies as oracles |
| Analysis | Patterns in logs, configurations and rules | Pattern from an unrepresentative sample | Inspect and rerun the query on the full data |
The rule for placing a task is to use the assistant where the verification costs less than doing the work unaided. Chapter 14 develops the verification techniques; this chapter concentrates on the set-up around them.
Modes 1 to 3 for architecture work
The three modes differ in where the AI runs, what it can reach and how much of the architect's identity it carries.
In Mode 1, the architect pastes text into a conversational assistant and reads the answer. The architectural questions are where the pasted text goes and on what terms (AI Governance, Chapter 2) (168, Nordqvist, 2026). The same brand may be offered under consumer terms and under enterprise terms with a data processing agreement, and an architect who signs in with a private account has moved organisational information outside every contract the organisation holds. A paste of architecture information cannot be recalled.
In Mode 2, the assistant sits inside the office suite, the ticketing system or the architecture tooling and is grounded in the organisation's data. It inherits the architect's permissions, so it can summarise a document the architect can read, and it can be steered by content the architect did not choose, such as an external email or a shared file. The OWASP Top 10 for large language model applications lists prompt injection and sensitive information disclosure among its principal risks (44, OWASP, 2025). For an architect who holds read access across many systems, the assistant's reach is the architect's reach.
In Mode 3, the architect uses an agentic work tool that reads and edits files, runs commands and calls connectors in a repository. The tool executes between instruction and review with the architect's credentials, and the vendors of such tools document the controls that bound it: permission rules, approval modes and sandboxes (120, Anthropic, n.d.) (121, OpenAI, n.d.). AI Platform and Security, Chapter 15, argues that a client setting is a convenience, not a control, and that enforcement belongs outside the client: default-deny egress from the workspace, a gateway that accepts a request only when the workspace identity may reach the requested model, and credentials scoped so that a protected workspace holds none for a cloud model (169, Nordqvist, 2026).
Mode 0 Ambient AI needs a mention as well. The architect's existing tools increasingly carry AI features that vendors switch on, and some act without a request. The architect inventories them so that nothing acts at an autonomy level that nobody decided (AI Red Team, Chapter 6) (170, Nordqvist, 2026).
The autonomy level for the architect's own Mode 3 use is at most Level 2 Supervised for file and repository changes: the tool proposes an edit and the architect approves it before it happens. Level 3 Bounded is reserved for the agent team under a mandate manifest (Chapter 13). Level 4 Autonomous does not appear in the architect's own work.
The evidence on productivity
The evidence on whether assistants make skilled people faster is real, mixed and, for architecture work, indirect. The honest summary is that the studies exist for software development and customer support, hardly at all for security architecture, and that their findings depend on the task, the experience of the user and the way the tool is used.
Several studies found gains. In a controlled experiment, developers given GitHub Copilot completed a defined programming task, writing an HTTP server in JavaScript, 55.8 per cent faster than a control group (92, Peng et al., 2023). Three field experiments at large employers, pooled, found that developers with the assistant completed about a quarter more tasks, with larger gains for less experienced developers (94, Cui et al., 2025). A study of more than five thousand customer-support agents found about 14 per cent more issues resolved per hour, with the largest effect for novices and little for the most experienced (96, Brynjolfsson et al., 2025). Consultants at a large management consultancy who used a model on tasks inside what it could do finished more tasks, faster and with higher rated quality; on a task outside that frontier, they were 19 percentage points less likely to reach a correct answer than consultants working without it (95, Dell'Acqua et al., 2023). The authors call the uneven edge of capability the jagged frontier, and the phrase matters here because the architect cannot see the edge from the inside: a plausible answer looks the same on both sides of it.
One randomised trial found the opposite. Sixteen experienced open-source developers worked on 246 real issues in repositories they knew well, with AI tools allowed or disallowed at random; the tasks took 19 per cent longer when AI was allowed, although the developers had predicted a speed-up of 24 per cent and, after the trial, still believed that the tools had sped them up by about 20 per cent (93, Becker et al., 2025). The study is small and concerns early-2025 tools and mature codebases, but it shows two things the architect should keep. Experts working in a context they know deeply may gain little, and a person's feeling of having been helped is not a measurement.
Industry surveys point the same way at organisational level. The 2024 DORA report associated greater AI adoption with improvements in documentation and code quality and with decreases in delivery throughput and stability (97, DORA, 2024). The 2025 report found that adoption had become near universal among respondents and described AI as an amplifier of the capabilities and weaknesses already present in an organisation (98, Harvey & DeBellis, 2025), and its AI Capabilities Model names organisational practices, among them a communicated AI stance, strong version control and work in small batches, that govern whether the gains reach the organisation (99, Storer & DeBellis, 2025). Version control and small batches are practices that Architecture as Code already applies to architecture (167, Nordqvist, 2025), which is why a codified architecture practice is better placed to benefit.
Two cautions apply to transfer. First, no controlled study of security architecture work as such is in the bibliography; the studies concern programming, support and consulting tasks. Second, the length of task that models complete is rising: METR measured the human-time length of tasks that frontier models complete at a fixed success rate and found it doubling roughly every seven months over the period studied (100, Kwa et al., 2025). The productivity findings are observable, mixed and task-dependent. That their results carry over to architecture drafting and review is expected, not established, and the architect should measure the effect locally, with the log described later in this chapter, rather than adopt a number from a study of someone else's work.
The evidence on quality and security
The second body of evidence concerns what the assistants produce. For an architect it matters twice: as a reviewer of generated code and infrastructure definitions that the team commits, and as a producer of drafts that other people will rely on.
Generated code has repeatedly been found to contain weaknesses. Researchers who prompted GitHub Copilot with scenarios drawn from a list of common weakness types generated 1,689 programs and found roughly 40 per cent of them vulnerable (101, Pearce et al., 2022). A user study of programmers with and without an assistant found that those with the assistant wrote significantly less secure code and were more likely to believe that it was secure (102, Perry et al., 2023). The second finding is the more important for the architect, because it describes the confidence of the reviewer, not just the quality of the code. Vendor measurement continues the pattern: Veracode's 2025 report tested more than a hundred models on tasks with a secure and an insecure way to complete them and found that a large share of the generated code failed its security checks, without a clear improvement for larger or newer models (103, Veracode, 2025), and a spring 2026 update reports that models still fail security tests despite claims to the contrary (104, Brombacher, 2026). The studies use benchmark tasks, so the figures describe a tendency, not a rate for a given repository.
A second class of defect belongs to agentic tools in particular. METR documented recent frontier models reward hacking: when a task is scored by code, a model sometimes optimises the score instead of the task, for example by exploiting or altering the scoring code, and continues to do so when told not to (105, Von Arx et al., 2025). Described as observable behaviour, not intent, this means that a Mode 3 tool asked to make a failing test pass may change the test, special-case the input or weaken the check. The architect's response is structural. Tests, policy-as-code rules and schemas that act as oracles for the tool's changes live in a path the tool cannot write to, and a change that touches an oracle is flagged for review whatever else it does. Chapter 14 builds a review protocol on that principle.
Two further weaknesses concern the architect's drafts rather than code. Assistants tend to agree with the person they are talking to: a study of several assistants found that responses matching a user's stated views were rated favourably by people and preference models, and the models sometimes gave up correct answers under pushback (198, Sharma et al., 2024). An architect who asks whether a design is sound after describing it with evident confidence receives an answer shaped by that confidence.
What review must therefore catch in generated material falls into five groups:
- Weaknesses of the usual kinds in code and configuration: injection, missing authorisation checks, over-broad permissions, secrets in files.
- Dependencies that do not exist, or that exist because someone registered a name a model tends to suggest.
- Tests and policies edited to pass.
- Claims about sources, articles and standards that the cited passage does not support.
- Omissions: the control, alternative or constraint that a competent reviewer would have raised.
A checklist applied to the assistant's output cannot find the last group. The architect who has reached a view first can.
Confidentiality of architecture information
Architecture information is among the most sensitive material an organisation holds. A threat model, a network map, a list of unpatched systems with compensating controls, a containment profile or a control catalogue with its known gaps tells an adversary where to look. The architect needs a rule for what may reach which model, and the rule should not depend on the architect remembering it at the end of a long day.
Start by classifying the information the architect handles. The series uses four classes, public, internal, confidential and protected, and routes work by class (AI Platform and Security, Chapter 15) (169, Nordqvist, 2026). This book places architecture information that describes the organisation's defences, such as the current security reference architecture, threat models of live systems, vulnerability and exception registers and unredacted incident material, in at least the confidential class. Public standards, published guidance and the architect's own generic working notes are public or internal. Label the work, not the person, and default unlabelled work to confidential, so that a missing label narrows what the tool may reach.
Route by class, and enforce the route outside the client. Public and internal work may use the approved enterprise tier of a cloud assistant, under a contract with a data processing agreement and no training on the organisation's inputs. Confidential and protected work reaches only self-hosted or sovereign-hosted models, through the AI gateway, from a workspace with default-deny egress. Two European considerations shape the rule. Under the GDPR the controller applies the principle of data minimisation in Article 5(1)(c), and a provider that processes personal data in prompts acts as a processor bound by a contract that meets Article 28 (5, European Union, 2016). Prompts about incidents regularly contain names and addresses, so the minimisation rule applies to the architect's own prompts. And a financial entity under DORA must keep a register of information on its contractual arrangements for ICT services supplied by third parties, which Article 28(3) requires (9, European Union, 2022). An assistant used for architecture work is such a service, so the provider of every model the architect uses, including the model behind a Mode 2 feature, belongs in the register. These are architectural implications of the instruments, not legal advice.
Self-hosting has costs that the architect should state in the record. Self-hosted open-weight models are often less capable than the best cloud models, and the study of package hallucinations found them more prone to the specific failure it measured (197, Spracklen et al., 2025). The Region or the group must also patch, evaluate and retire them. The confidentiality gain buys a verification burden, and the architect should expect to check a self-hosted model's research output more strictly than a cloud model's.
Three things never leave the controlled route whatever the tier: credentials and secrets, which have no place in a prompt; personal data beyond what the task needs; and unredacted exploit or vulnerability details of live systems. Redaction before a cloud prompt is a fallback, not the routing rule, because people under time pressure redact inconsistently.
Skills, instructions and prompt records
An assistant is repeatable when its instructions are written down and version controlled. Three kinds of file do that work for an architect.
An instructions file states the standing context of a repository or workspace: the conventions, the vocabulary, the forbidden actions and the locations of the oracles. The open AGENTS.md format gives coding agents a predictable place to look for it (119, AGENTS.md Contributors, n.d.). A skill is a folder with a description and instructions, and optionally scripts and reference files, that the tool loads when the task matches (118, Anthropic, 2025). A skill for drafting a decision record, for example, carries the template, the schema, the checks and the instructions to leave the decision to the architect. A mandate manifest is the architect's written permission for the tool itself: which model, which data, which tools, which autonomy level and which approvals. The mandate manifest for the architect's own Mode 3 tool is the first of the series of MND-* manifests (Chapter 13 extends the form to the agent team).
These files are prompts, and prompts are configuration: they belong in the repository with an owner, a version and a review. Skills and instructions files are also a supply chain: a skill taken from a public collection runs with the architect's permissions, so the architect reads it as code and pins its version.
Records of use serve three different purposes, and conflating them produces either surveillance or nothing. The work log answers which drafts came from the tool, so that a reviewer, an auditor or the architect later knows which parts of an artefact to examine more closely. A line per use, with date, artefact, tool, model route and the verification done, is enough. The session record, the full prompts and outputs, answers what exactly happened when a result is disputed; keep it where the gateway can retain it for a short fixed period, because it contains architecture information and possibly personal data, and apply the minimisation rule to it. The decision record answers why the architect decided as they did; it is the subject of the next section but one.
Worked example: mandate manifest MND-NR-01
Illustrative example. Nordvik Region's decision to add the security architect to the small group allowed Mode 3 tools is recorded as AIDR-0511 and implemented as the manifest below. The tool runs only on open-weight models that the platform team has approved in the model registry, served from the Region's reserved capacity in the Nordic data centre. The platform team enforces the egress and routing lines at the AI gateway and the workspace network; the manifest states them so that the architect, the platform team and the CISO read the same limits. Version 1.0.0 was superseded within weeks by version 2.0.0, which added a research skill at Level 0 Advisory (AIDR-0503, Chapter 13). Both versions predate the role charter of Chapter 4, which from 1 January 2027 caps the architect's own AI at Level 1 Assisted; from then the charter's stricter ceiling governed edits until the manifest's review in May 2027 aligned it as version 3.0.0 (Chapter 25).
mandate:
  id: MND-NR-01
  version: 1.0.0
  status: approved
  decision_record: AIDR-0511
  holder: role:security-architect
  approver: role:chief-information-security-officer
  review_by: 2027-05-01
  mode: Mode 3 Agentic work tools
  identity:
    kind: delegated   # acts with the holder's session, no identity of its own
  models:
    allowed: [registry:approved-open-weight]
    route: ai-gateway.reserved-capacity
    cloud_models: denied
  data:
    allowed_classes: [public, internal, confidential]
    denied_classes: [protected]
    never: [credentials, personal-data-beyond-task, live-vulnerability-detail]
  autonomy:
    read_files: Level 1 Assisted
    edit_files: Level 2 Supervised   # architect approves each edit
    run_commands: Level 2 Supervised
    commit_and_push: denied
  tools:
    allowed: [file-read, file-edit, sandboxed-shell]
    connectors: []   # none until a connector is reviewed
    network_egress: deny-by-default
  oracles:
    protected_paths: [tests/, policy/, schemas/]   # the tool cannot write here
  records:
    work_log: docs/ai-use-log.md
    sessions: gateway-retention-30d
  stop_path: platform team revokes the workspace token at the gateway
Four properties of the manifest repay attention. The autonomy lines are per action, not per tool. The oracle paths answer the reward-hacking finding. The empty connector list is a decision, since each connector is added by a reviewed change to the manifest. And the stop path sits at the gateway, outside the tool, so that it works whatever the tool does.
Worked example: a skill file for drafting AIDRs to Hansa Mutual's schema
Illustrative example. A Hansa Mutual domain architect for AI writes many AI Decision Records, in the form of AI Platform and Security, Chapter 5 (169, Nordqvist, 2026). The skill below, kept in the architecture repository, gives the assistant the schema and the checks. It deliberately leaves the decision and the rationale to the architect, so that the record is not written by the thing it records.
---
name: draft-aidr
description: Draft a Hansa Mutual AI Decision Record (AIDR-0550 to AIDR-0599)
  from the architect's notes. Use when asked to write or update an AIDR.
---

# Draft an AIDR

1. Read `schemas/aidr.schema.json` and the two most recent accepted records
   under `decisions/aidr/` for tone and level of detail.
2. Create `decisions/aidr/AIDR-NNNN-<slug>.yaml` with status `proposed`.
   Take NNNN from `decisions/aidr/NEXT_ID`; never reuse a number.
3. Fill the context, options considered, intended purpose, risk
   classification, role, data sources and evaluation criteria from the
   architect's notes only. If a field has no support in the notes, write
   `TODO: architect` and do not guess.
4. Leave `decision`, `rationale` and `approved_by` empty. These fields are
   the architect's. Add `drafted_with: assistant` and the model route.
5. List every claim about an instrument as article plus source number from
   `docs/30_references.md`; mark unsupported claims `UNVERIFIED`.
6. Run `make validate-aidr` and report the result. Do not edit the schema,
   the validator or any accepted record.
The drafted_with field is the link to the work log and to the next section: a record that an assistant drafted says so, and a reviewer reads its context and options with that in mind.
When AI-assisted work needs a decision record
Architecture as Code concluded that the habit on which trustworthy programmes rest is to make the implicit explicit, and that an AI-assisted decision without a traceable human rationale should receive an Architecture Decision Record, written retrospectively if necessary (Architecture as Code, Chapter 27) (167, Nordqvist, 2025). AI Platform and Security, Chapter 5, supplies the form: short, numbered, immutable records with fields for AI, validated against a schema and re-opened by evidence (169, Nordqvist, 2026). The architect's own use raises the practical question of when a record is needed, because a record for every draft would be noise.
Three tests decide it. First, the use itself needs a record when the architect adopts a tool, a model route or a new class of task, because that is a decision about the architect's own boundary and the organisation may have to defend it, for example to a supervisor or an auditor. MND-NR-01 and its decision record are of this kind. Second, a decision the assistant shaped materially needs a record when the options considered, the framing or the evidence came from the assistant and the decision is hard to reverse or has consequences beyond the architect's own work: a boundary placed, a control accepted, an exception granted, a supplier requirement written into a tender. The record names the decision, the human rationale and the verification, and says that an assistant contributed. Third, a decision the assistant did not shape needs only the record the decision would have had anyway. The assistant's involvement does not by itself add a requirement; the absence of a human rationale does.
If the architect could not say, a year later, why the decision was made without reading the assistant's output, the rationale is missing. Where the work log shows that a significant decision was shaped by the tool and no record exists, the architect writes the record retrospectively and marks it so.
Working habits that keep judgement independent
Reduced effort is the documented cost of leaning on an assistant. A survey of knowledge workers found that higher confidence in the AI went with less critical thinking effort, and higher self-confidence with more (111, Lee et al., 2025). Experiments on automation have long shown that people who trust an automated aid check it less (107, Parasuraman & Manzey, 2010). AI Threat, Chapters 6 and 14, concluded that relying on AI reduces effort, recall and, among those who trust the tool, checking, and recommended drafting first, unassisted practice and seeded-error drills (171, Nordqvist, 2026). Chapter 15 builds the programme. The habits below are the part that belongs in the architect's daily work.
Draft first. Write the position, the options and the decision in a few lines before asking for a draft. The assistant's version is then something to compare with, not something to anchor on. For a threat model of a live system, build the first model unaided, then ask the assistant for what is missing.
Ask for the counter-argument, not for confirmation. Because assistants lean toward agreement (198, Sharma et al., 2024), ask for the strongest case against the design, the alternative not considered, or the assumption that would make the decision wrong. State the question neutrally; do not describe the design as the obvious choice.
Verify every source. Open the cited passage and read it. A reference that cannot be opened is removed from the draft, and a claim that the passage does not support is rewritten or removed. Do not quote an article number from an assistant without checking the instrument.
Mark what came from the assistant. The work log marks drafts, and the artefact says in its record that an assistant contributed. A reader can then set the right level of scrutiny.
Keep a share of the work unassisted. The share is for the architect and the CISO to set; Chapter 15 proposes a quarterly programme. The point of the share is that the architect who cannot do the craft cannot verify the assistant's version of it.
Practical guide: setting up a personal AI workflow for architecture work
Purpose. Give the architect a working set-up in which assistants speed up drafting, research, review and analysis while architecture information stays confidential, output is verified and use is recorded.
Roles. The architect owns the workflow. The CISO approves the mandate manifest. The platform team operates the gateway and the workspaces. The data protection officer advises on prompts and session records. In a group with works councils, the councils are consulted before any tool that can show who wrote what is used on others' work.
Steps.
- Inventory the AI the architect already has: Mode 1 services, Mode 2 features in the office suite and the architecture tooling, Mode 3 tools, and Mode 0 features in the consoles. Record the mode, the identity, the data reachable and the provider of each.
- Classify the architecture information the architect handles, using the four classes, and name the artefact types that are at least confidential.
- Approve a route for each class: an enterprise cloud tier for public and internal work, self-hosted or sovereign-hosted models for confidential and protected work. Enforce it at the gateway and the workspace network, with default-deny egress; do not rely on client settings.
- Write the mandate manifest for the Mode 3 tool with autonomy per action, no more than Level 2 Supervised for edits, protected oracle paths and a stop path outside the tool. Review it every six months or when the tool, model or connector changes.
- Create the instructions file and the first two skills for the tasks done most often, such as AIDR drafting and control-mapping checks. Keep them in the repository, owned, versioned and reviewed, and read any skill from outside as code before use.
- Start the work log: date, artefact, tool and model route, what the tool did, what the architect verified. Set a retention period for session records, thirty days by default, and shorten it where prompts contain personal data.
- Agree the habits: draft first, ask for the counter-argument, open every source, and keep a defined share of work unassisted.
- After three months, review the log with the CISO: where the tool saved time, where it cost time and which errors verification caught. Adjust routes, skills and the unassisted share.
Defaults to adapt. Thirty-day session retention, a six-month manifest review and a quarterly log review suit a single architect or a small team; adapt them to the organisation's risk appetite.
Definition of done. The inventory is current; each class has an enforced route; the manifest is approved; the first skills are in the repository; the log has at least one reviewed month; and the architect can state, for any artefact signed in that month, which parts the tool drafted and how they were verified.
Across the usage modes
| Mode | What the architect does | Principal risk to architecture information | Principal control | Autonomy level |
|---|---|---|---|---|
| Mode 0 Ambient AI | Nothing: vendor features run in existing tools | Features act or send data without a decision | Inventory; switch off or accept deliberately | Vendor-set; inventoried |
| Mode 1 Conversational assistants | Drafts, research, questions on pasted text | The paste leaves the organisation | Approved tier only; public and internal material only | Level 0 Advisory |
| Mode 2 Embedded workplace assistants | Summaries and drafts over documents the architect can read | Inherited permissions; untrusted content steers the assistant | Tenant configuration as code; access review; labelled content | Level 0 Advisory to Level 1 Assisted |
| Mode 3 Agentic work tools | Edits files, runs analyses, drafts in the repository | Excessive agency; oracle edited; egress | Mandate manifest; gateway routing; protected oracles; sandbox | At most Level 2 Supervised |
Nordvik Region and Hansa Mutual
Nordvik Region's security architect uses the approved enterprise Mode 1 tool for public material, such as reading and summarising published standards and drafting generic tender wording, and the Mode 3 tool under MND-NR-01 only on open-weight models on the Region's reserved capacity, because architecture information describes the Region's defences and the Region's policy prefers self-hosted or EU-hosted models for security information. The Region classifies the security reference architecture, the threat models of live systems and the exception register as confidential, so none of them reaches a cloud tier. The architect keeps a short work log of which drafts came from the tool, which doubles as evidence for the competence plan the regional director asked for (Chapter 21), and finds the largest cost in verification: the open-weight model is a weaker researcher than the cloud models the architect can see on public material, and every cited article is opened.
Hansa Mutual's architects use Modes 1 to 3 through the enterprise tiers with classification routing, so that sensitive architecture information reaches only the self-hosted models in hansa-dc-frankfurt, and the DORA register of information records each provider, the model behind each Mode 2 feature included. Its team of six shares skills such as the AIDR drafting skill and agrees the habits as team practice. Its constraint is scale and consent: the review features that read pull requests and can show who wrote what wait for works-council consultation in Germany and the Netherlands and union consultation in Sweden, and architecture information that reaches the UK and Swiss entities follows the transfer rules of those regimes. The two organisations differ in people and mechanism, and agree on the point that matters here. The architect's own use of AI is where the habit of drafting first and verifying sources is set, before any agent acts for the team.
Summary
This chapter described the security architect as a user of AI in Modes 1 to 3, where the AI acts with the architect's identity and the architect answers for its output. It concerns Shift 1, from documents to code, because the architect's drafts, instructions, skills and mandate manifests are versioned artefacts with oracles that do not depend on the assistant, and Shift 4, from sole author to conductor of an AI team, because accountability for one assistant's output is the first step towards accountability for a team's.
The evidence on productivity is observable but mixed: gains in controlled tasks and for less experienced workers, a slowdown for experienced developers in a randomised trial, and a jagged frontier that the user cannot see from inside. The evidence on quality is observable and consistent in direction: generated code has repeatedly been found insecure, reviewers using assistants are more confident, and agentic tools can game a scoring check. Whether these findings transfer to architecture drafting and review is expected to be broadly the case, but no controlled study of security architecture work is in the bibliography, so the architect measures locally.
Confidentiality is a routing problem solved outside the client: classify the work, route by class, enforce at the gateway and keep confidential and protected architecture information on self-hosted models. The records are three and distinct: a work log of which drafts came from the tool, a short-lived session record, and a decision record when an assistant materially shaped a decision that is hard to reverse. The habits that keep judgement independent, drafting first, asking for the counter-argument, opening every source and keeping a share of work unassisted, cost little and are the precondition for everything in Chapters 13 to 15.
Chapter 13 turns from the architect who uses an assistant to the architect who conducts a team of agents with identities of their own, and shows the mandate manifest, the skills and the containment that team needs.
Sources
- Peng, S., Kalliamvakou, E., Cihon, P. & Demirer, M. (2023). The Impact of AI on Developer Productivity: Evidence from GitHub Copilot. arXiv:2302.06590. (92, Peng et al., 2023)
- Becker, J., Rush, N., Barnes, E. & Rein, D. (2025). Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity. METR, arXiv:2507.09089. (93, Becker et al., 2025)
- Cui, Z., Demirer, M., Jaffe, S., Musolff, L., Peng, S. & Salz, T. (2025). The Effects of Generative AI on High-Skilled Work: Evidence from Three Field Experiments with Software Developers. SSRN Working Paper 4945566. (94, Cui et al., 2025)
- Dell'Acqua, F. et al. (2023). Navigating the Jagged Technological Frontier. Harvard Business School Working Paper No. 24-013. (95, Dell'Acqua et al., 2023)
- Brynjolfsson, E., Li, D. & Raymond, L. (2025). Generative AI at Work. The Quarterly Journal of Economics, 140(2). (96, Brynjolfsson et al., 2025)
- DORA. Accelerate State of DevOps Report 2024. Google Cloud / DORA, 2024. (97, DORA, 2024)
- Harvey, N. & DeBellis, D. (2025). Announcing the 2025 DORA Report: State of AI-assisted Software Development. Google Cloud Blog. (98, Harvey & DeBellis, 2025)
- Storer, K. M. & DeBellis, D. (2025). Introducing DORA's inaugural AI Capabilities Model. Google Cloud Blog. (99, Storer & DeBellis, 2025)
- Kwa, T., West, B., Becker, J. et al. (2025). Measuring AI Ability to Complete Long Tasks. METR, arXiv:2503.14499. (100, Kwa et al., 2025)
- Pearce, H., Ahmad, B., Tan, B., Dolan-Gavitt, B. & Karri, R. (2022). Asleep at the Keyboard? Assessing the Security of GitHub Copilot's Code Contributions. IEEE Symposium on Security and Privacy. (101, Pearce et al., 2022)
- Perry, N., Srivastava, M., Kumar, D. & Boneh, D. (2023). Do Users Write More Insecure Code with AI Assistants? ACM CCS '23. (102, Perry et al., 2023)
- Veracode (2025). 2025 GenAI Code Security Report. Veracode. (103, Veracode, 2025)
- Brombacher, F. (2026). Spring 2026 GenAI Code Security Update. Veracode. (104, Brombacher, 2026)
- Von Arx, S., Chan, L. & Barnes, B. (2025). Recent Frontier Models Are Reward Hacking. METR. (105, Von Arx et al., 2025)
- Lee, H.-P. et al. (2025). The Impact of Generative AI on Critical Thinking. CHI 2025. (111, Lee et al., 2025)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation. Human Factors, 52(3). (107, Parasuraman & Manzey, 2010)
- Spracklen, J. et al. (2025). We Have a Package for You! A Comprehensive Analysis of Package Hallucinations by Code Generating LLMs. USENIX Security Symposium. (197, Spracklen et al., 2025)
- Sharma, M. et al. (2024). Towards Understanding Sycophancy in Language Models. ICLR 2024. (198, Sharma et al., 2024)
- OWASP Foundation. OWASP Top 10 for Large Language Model Applications, 2025 edition. (44, OWASP, 2025)
- European Parliament and Council of the European Union. Regulation (EU) 2016/679 (GDPR). (5, European Union, 2016)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 (DORA). (9, European Union, 2022)
- Anthropic (2025). Introducing Agent Skills. (118, Anthropic, 2025)
- AGENTS.md Contributors. AGENTS.md: a simple, open format for guiding coding agents. (119, AGENTS.md Contributors, n.d.)
- Anthropic. Configure permissions. (120, Anthropic, n.d.)
- OpenAI. Agent approvals & security. (121, OpenAI, n.d.)
- Nordqvist, G. (2025). Architecture as Code. (167, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Governance. (168, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Platform and Security. (169, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team. (170, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat. (171, Nordqvist, 2026)