Threat Modelling Transformed: Continuous, Generated and AI-Assisted
Threat modelling is the security architect's oldest analytical tool and the one whose output has aged worst. A workshop produces a document, the document describes the system on the day of the workshop, and within weeks a retrieval source is added, an agent is given a new tool or a permission is widened and the document describes a system that no longer exists. This chapter concerns three of the four shifts. Shift 1, from documents to code, because the threat model becomes a versioned artefact generated from the architecture repository and tested by the pipeline. Shift 3, from periodic to continuous, at machine speed, because the model is regenerated on every change that moves a boundary rather than once per project. And Shift 4, from sole author to conductor of an AI team, because an AI proposes candidate threats and the architect remains the accountable verifier of every one of them.
The chapter answers five questions: what STRIDE, attack trees, MITRE ATT&CK and MITRE ATLAS each contribute in 2026; how a threat model is generated from architecture code and regenerated on change; what AI adds and what a person must still decide; when a threat model should fail the pipeline; and how AI-specific and agentic threats, such as prompt injection, are modelled at the level needed to design controls. It builds on the conclusions that threat models belong in code beside the architecture (167, Nordqvist, 2025), that every threat names a control and every control an owner (169, Nordqvist, 2026), and that AI proposes while a named reviewer decides (170, Nordqvist, 2026). It leaves the model and the policies that generate the input to Chapter 5, the design of the boundaries themselves to Chapter 7, the control catalogue to Chapter 9 and the general techniques for reviewing AI output to Chapter 14.
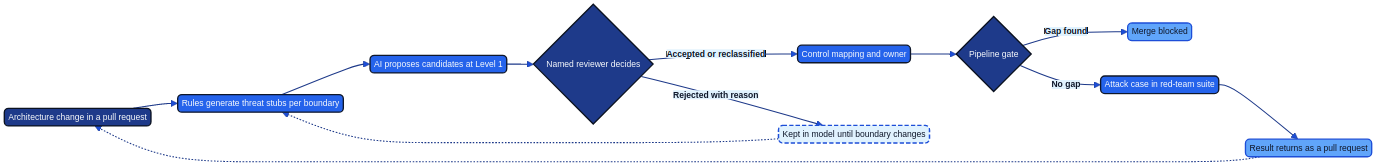
Figure 6.1: The threat-modelling loop. A change to the architecture regenerates the model, an AI proposes candidates, a named reviewer decides, the pipeline gate blocks gaps and every accepted threat becomes an attack case whose result returns as a pull request.
What threat modelling was for
The Threat Modeling Manifesto frames the practice around four questions: what are we working on, what can go wrong, what are we going to do about it, and did we do a good enough job (49, Threat Modeling Manifesto Working Group, 2020). Shostack teaches the same four (71, Shostack, 2014). The manifesto's own values already point away from the document: it prefers "a journey of understanding over a security or privacy snapshot" and "continuous refinement over a single delivery" (49, Threat Modeling Manifesto Working Group, 2020). What practice lacked was a way to make refinement cheap. A workshop needs the right people in a room for a day, so it happens once, at design time, and its output is filed. The question "did we do a good enough job" is then never asked again about the system as it became.
Regulation has made the snapshot harder to defend. Article 9 of the AI Act requires a risk management system for high-risk AI systems and describes it in Article 9(2) as a continuous iterative process planned and run throughout the lifecycle, with regular systematic review and updating (1, European Union, 2024). NIS 2 Article 21(2)(a) lists policies on risk analysis and information system security among the measures that essential and important entities must take (6, European Union, 2022). DORA Article 8(7), for the financial entities that Hansa Mutual operates in the EU, expects an ICT risk assessment upon each major change to network and information system infrastructure (9, European Union, 2022). These are architectural implications, not legal advice, and they share one: an organisation that can show only an annual workshop cannot show that each significant change was considered. A model regenerated on every change can.
Three developments make that possible: the architecture is increasingly code (Chapter 5), the pipeline can check every pull request, and an AI can propose candidate threats in minutes, which no reviewer team can do by hand. None removes the workshop. It moves from producing the document to deciding what the generated model cannot hold: the business impact of a failure, the abuse cases that depend on how people really use a system, and the assumptions about adversaries. The manifesto's preference for people and collaboration over process stands.
A shared vocabulary
A threat model is useful to the extent that other people can act on it, and that requires shared names. Five vocabularies cover most of what an architect needs, and each answers a different question.
| Vocabulary | What it contributes | Question it answers | Limit |
|---|---|---|---|
| STRIDE (50, Microsoft, 2017) | Six categories of harm at a boundary: spoofing, tampering, repudiation, information disclosure, denial of service, elevation of privilege | What can go wrong here? | Names the harm, not how an adversary reaches it |
| Attack trees (179, Schneier, 1999) | A goal decomposed into alternative and combined steps | How could this goal be reached, and which route is cheapest? | Costly to draw; reserved for a few high-value goals |
| MITRE ATT&CK (46, MITRE, n.d.) | Adversary tactics and techniques observed against enterprise estates | Which technique, and is it detected? | Not specific to AI |
| MITRE ATLAS (47, MITRE, n.d.) | Tactics, techniques and case studies for attacks on AI-enabled systems | How is the model, its data or its pipeline reached? | Young and still changing |
| MITRE D3FEND (48, MITRE, n.d.) | A knowledge graph of defensive countermeasures | Which family of countermeasure answers this technique? | Describes families, not your configuration |
STRIDE names the harm, ATT&CK and ATLAS name how an adversary produces it and D3FEND names what answers it. For AI systems two further catalogues give the weaknesses seen in deployed applications: the OWASP Top 10 for Large Language Model Applications, whose 2025 edition runs from LLM01 prompt injection to LLM10 unbounded consumption (44, OWASP, 2025), and the OWASP Top 10 for Agentic Applications, which adds the risks that come from tools, delegated identity and multi-step autonomy (45, OWASP, 2025). NIST's adversarial machine learning taxonomy supplies terminology for attacks on predictive and generative models, so that a tender annex says the same thing as the threat model (30, Vassilev et al., 2025). The Microsoft AI Red Team's taxonomy of failure modes in agentic systems separates security from safety failures, which helps when a threat is an agent doing the wrong thing under its own mandate and not an attack at all (117, Microsoft, 2025).
Two practices make the vocabulary work in a pipeline. The first is to pin the catalogue versions in the repository and fail the build when a threat cites an identifier that does not exist in the pinned version, because ATT&CK, ATLAS and OWASP all change between releases. The second is to record the vector as a class of behaviour and never as an operational recipe. A threat entry says that instructions embedded in a claimant-supplied document could steer an agent; it does not contain the instructions. That is enough to design a control, a detection and a test, and it keeps the threat model something that can be shared with a supplier, an auditor and a works council without being an attack manual.
The technique identifiers also connect the model to the rest of the security organisation: a detection-engineering team can look up whether a detection exists, a red team can choose the technique as a scenario and a tender annex can name a D3FEND family. Attack trees remain valuable where one goal justifies the labour, such as reaching the identity provider's administration plane, and are poor value as a default.
Threat models generated from the architecture
The input to generation is the architecture model that Chapter 5 builds. In a Structurizr workspace (60, Structurizr, n.d.) the elements are people, software systems, containers and agents, the relationships are the data flows, and properties attached to elements carry the security facts: the trust zone, the data classification, the identity the element runs as and the markets it serves. A threat model needs exactly these facts. Where the workspace lacks them, the first result of generation is a list of elements for which no threat can be derived, which is a useful finding in its own right.
Generation works in two layers. The first is deterministic. For every relationship that crosses a trust-zone boundary, a rule emits a boundary record. For each boundary and each element type, a table of STRIDE applicability rules emits a threat stub with the techniques the pinned catalogues associate with it. The result is compared with the last accepted model: unchanged stubs keep their earlier decisions, new stubs become candidates, and stubs whose boundary has disappeared are retired with a note. Open-source tools such as OWASP pytm and Threagile take this approach, describing the system in code and deriving threats from rules (178, OWASP, n.d.) (180, Schneider, n.d.). The second layer is the AI, treated in the next sections, which adds candidates the rules cannot derive.
Stability matters more than it appears. A threat needs an identifier that survives regeneration, so that a decision recorded last month still attaches to the same threat today. A practical rule derives the identifier from the boundary, the STRIDE category and the technique. Without it, every regeneration looks like a fresh workshop and reviewers lose the history that makes review fast.
Regeneration is triggered by the changes that alter the threat surface, which the model names as review triggers: a data flow added, a retrieval source added, a tool or a permission granted to an agent, a model version changed, a market added, a trust zone redefined. A code-ownership rule routes any pull request that touches those paths to the security architect (174, GitHub, n.d.), the mechanism AI Platform and Security, Chapter 17, used to make the threat model "reviewed as often as the system changes" (169, Nordqvist, 2026).
Generation has limits that the model must state. It cannot see a data flow that nobody modelled, so drift between the workspace and the estate (Chapter 5) produces blind spots that look like completeness. It cannot see inside a supplier's system, where the workspace shows a black box with contractual properties. And it cannot see people: the claims handler who forwards an attachment by email, or the caseworker who pastes a case into an assistant that is not approved. The model records these as explicit assumptions and as tasks for the workshop.
Modelling AI and agentic systems
An AI system adds a property that classical models lack: natural language is both the data and the instruction channel, and the model has no reliable way to separate the two. Greshake and colleagues showed that content retrieved by an LLM-integrated application can carry instructions that steer it, without the user or the operator writing them (123, Greshake et al., 2023). AI Platform and Security, Chapter 16, concluded from this that prompt injection is a property of the architecture and not a patchable defect, that the controls therefore sit outside the model, and that loading a model is itself code execution (169, Nordqvist, 2026). For the threat model the consequence is practical: every place where content can enter the model's context is a trust boundary, whoever is meant to write that content.
Six boundaries recur, and the generator walks all of them.
| Boundary | What to ask | Typical vocabulary entries | Mitigation family |
|---|---|---|---|
| Retrieval ingest | Who can write to the sources the index reads? | LLM01, LLM08; ATLAS prompt injection, indirect | Treat indexed content as untrusted data; entitlement filtering before retrieval |
| Prompt assembly | What reaches the context besides the user's input? | LLM01, LLM07 | Structured templates; no secrets in prompts |
| Model endpoint | Who operates it, and where does the data go? | LLM02, LLM10 | Gateway controls; sovereignty and contract terms |
| Tool call | What can the agent change, with whose credential? | LLM06; OWASP agentic risks | Policy decision point outside the model; task-scoped credentials |
| Output into a system of record | Does model output acquire authority on arrival? | LLM05, LLM09 | Schema validation; human approval for consequential actions |
| Model and adapter loading | What code runs when weights are loaded? | LLM03; ATLAS supply chain compromise; ATT&CK supply chain compromise | Signed artefacts, provenance, isolated loading |
The Simon Willison formulation of the "lethal trifecta" gives agentic systems a test that fits one line in the model: an agent that has access to private data, is exposed to untrusted content and can communicate externally can be steered into disclosing the data (124, Willison, 2025). The threat model records, for each agent, which of the three legs are present and which control removes the others. Security researchers have disclosed cases that follow this pattern: a zero-click injection through content received by a workplace assistant (125, Reddy & Gujral, 2025), and an injection through a public repository issue that led an agent with a repository connector to read private repositories (126, Milanta & Beurer-Kellner, 2025). Both are lessons at the level of the class, and neither needs reproducing here.
A Mode 5 agent acts with an identity and permissions of its own, so the model treats it as a privileged machine insider that can be manipulated or compromised and scores its permissions as if an adversary held them. Layered frameworks such as MAESTRO help to enumerate where agentic systems can fail across models, tools, memory, orchestration and the environment (181, Huang, 2025), and the OWASP agentic list and the Microsoft taxonomy give the same enumeration a second reading. The mitigations that follow from the architecture are the ones AI Red Team, Chapters 13 and 28, concluded must hold: a policy decision point outside the model, permission manifests that set a ceiling on every action, and red-team campaigns that test the ceiling (170, Nordqvist, 2026). Chapter 7 designs them; the threat model is where their absence is found.
AI-assisted threat modelling
An AI adds five things to the loop. It covers every pull request, which a human team cannot. It translates a boundary into the vocabularies of the previous section, proposing a STRIDE category, a technique, an OWASP identifier and a mitigation family together. It reads unstructured material, such as a supplier's architecture description, a tender response or an incident report, and proposes the elements and flows they imply, flagged as unverified. It writes the difference between two model versions in plain language, which is what a reviewer needs. And it can be asked to draft the case against a rejected threat, so that a rejection is tested. This is Shift 4 in this craft: the architect conducts a threat-modeller agent (Chapter 13) and does not draft every line.
The limits are as concrete. The AI works only from what the inputs contain. Nothing in them tells it the organisation's risk appetite, which flows exist but were never modelled, whether a control works in production or how a particular adversary will adapt. A model asked for threats produces plausible text whether or not the threat is grounded in the architecture, which is why grounding is checked mechanically against the workspace before a reviewer sees the candidate. Its candidates also tend toward the generic, true of any system and decisive for none. Parasuraman and Manzey found that people using automated aids show complacency and automation bias (107, Parasuraman & Manzey, 2010), and a long list of fluent candidates invites exactly that. The loop therefore shows each candidate beside its provenance and asks for a reason with every acceptance. Chapter 14 sets out the techniques for verifying AI proposals that do not rely on trusting the proposer, among them independent re-derivation and seeded errors.
On autonomy, the rule from AI Red Team, Chapter 10, holds: the generator works at Level 1 Assisted. It writes to a pull request comment or a branch and never to the accepted model or the risk register, and no AI accepts a threat, a risk or an exception (170, Nordqvist, 2026). The generator is itself an AI system with a threat model. It reads architecture information that describes the organisation's defences, so it runs on infrastructure trusted with that material, which for Nordvik Region means self-hosted capacity. It also reads content from outside, such as supplier documents and threat reports, and everything security AI reads may be written by the adversary (170, Nordqvist, 2026). Its outputs are therefore proposals from a source that can be steered.
The evidence on quality is thin. AI Red Team, Chapter 10, describes the design of the loop and the soundness checks, but systematic comparison of AI-proposed threats with those from expert workshops is limited, and this book treats it as an open question. The response is local measurement: the share of candidates accepted, amended and rejected, the threats later found by a red team, an incident or an audit that no candidate covered, and the time reviewers spend.
Deciding candidate threats
Soundness is defined before the first candidate arrives. The six criteria are those AI Red Team, Chapter 10, set out (170, Nordqvist, 2026). A candidate is grounded when it refers to a component, boundary, identity or data flow that exists in this version of the workspace. It is correctly classified when its STRIDE category and technique identifiers fit the vector described. Its mitigation belongs to the right family, so that a threat about model behaviour does not propose "improve the system prompt" in place of a control outside the model. Its likelihood and impact rest on a named basis, an assumption or an asset rating that is current. The set of candidates is complete for the boundaries that changed. And the result is stable, so that a score changes between versions only for a stated reason. The mechanical parts of grounding, classification, completeness and stability are automated; the judgement about mitigation family and about likelihood and impact is the reviewer's.
The reviewer is a named person. Chapter 4 assigns the decision right in the role charter, and the code-ownership rule makes it operational. A candidate has four possible outcomes, and each is recorded with a reason.
| Outcome | Meaning | Recorded |
|---|---|---|
| Accepted | The threat is real for this architecture and enters the model | Reviewer, reason, controls |
| Reclassified | The threat is real but the category, technique or boundary was wrong | Original and corrected classification, reason |
| Rejected | The threat does not apply in this architecture | Reason and a revisitWhen trigger |
| Deferred | Information is missing | Owner and a date, after which the pipeline blocks |
A rejected candidate stays in the file, so that regeneration does not raise it again, an auditor can see it was considered and the revisitWhen trigger brings it back when the justifying fact changes. Acceptance of a residual risk is a different decision and belongs to the risk owner, with an expiry date. The AI does not make either decision. Review quality is measured, because a reviewer who accepts forty candidates in a minute is not reviewing: the time per decision, the share accepted unchanged and the rate at which a second reviewer overturns a sampled decision are signals, not targets.
Worked example: A threat model as code for Hansa Mutual's claims-triage agent
The following illustrative excerpt belongs to the claims-triage agent, the Mode 5 system that works on the core claims system through the Polish service centre (AIDR-0024). The pull request that triggered regeneration added a claimant-document intake path to the workspace. The threat-modeller agent of the architecture review team proposed three candidates under its mandate MND-HM-01; the AI domain architect decided each.
# Illustrative: Hansa Mutual, threat-model.yaml for the claims-triage agent (excerpt)
kind: ThreatModel
system: claims-triage-agent               # Mode 5, AIDR-0024
workspace: hansa-estate@7c41d90           # Structurizr commit it was generated from
version: 6.2.0
reviewTrigger: [retrieval_sources, tools, permissions, model_version, markets]
changedBoundaries: [TB-11]
legs: {private_data: true, untrusted_content: true, external_comms: false, cutBy: CTRL-NET-004}
boundaries:
  - {id: TB-11, from: claimant-document-intake, to: triage-agent}
  - {id: TB-12, from: triage-agent, to: core-claims-adapter}
threats:
  - id: T-101
    boundary: TB-11
    stride: tampering
    owasp: LLM01
    atlas: AML.T0051.001                  # indirect prompt injection
    vector: Instructions embedded in a document supplied by a claimant
    impact: Route or approval-rule outcome steered away from the handler's view
    proposedBy: {agent: threat-modeller, mandate: MND-HM-01, inputs: [7c41d90, atlas-pinned]}
    review: {decision: accepted, by: ai-domain-architect, reason: intake is claimant-writable}
    controls: [CTRL-AGT-002, CTRL-AGT-011, CTRL-RAG-006]
    residual: low
    verifiedBy: HM-SEC-003/claims-intake-014
  - id: T-102
    boundary: TB-12
    stride: elevation_of_privilege
    owasp: LLM06
    vector: Tool call accepted for a market other than the claim's
    proposedBy: {agent: threat-modeller, mandate: MND-HM-01, proposedStride: spoofing}
    review: {decision: reclassified, by: ai-domain-architect, reason: call is bound to market, not identity}
    controls: [CTRL-AGT-011]
    residual: low
    verifiedBy: HM-SEC-003/claims-market-007
  - id: T-103
    boundary: TB-11
    stride: information_disclosure
    owasp: LLM02
    vector: Claim data leaves through an outbound channel
    proposedBy: {agent: threat-modeller, mandate: MND-HM-01}
    review: {decision: rejected, by: ai-domain-architect, reason: no outbound tool in the manifest, revisitWhen: tools}
controls:
  CTRL-AGT-002: {owner: group-ai-platform, text: Actions outside the approval rules need handler approval}
  CTRL-AGT-011: {owner: claims-security-architect, text: Tool calls and delegated tokens bound to the claim's market}
  CTRL-RAG-006: {owner: group-ai-platform, text: Intake content indexed as untrusted data, never as instructions}
  CTRL-NET-004: {owner: platform-security-architect, text: Default-deny egress for the agent's workload}
The legs line records the trifecta for this agent: it holds private data and reads untrusted content, and the architecture cuts the third leg by denying egress, which is why T-103 is rejected and why revisitWhen: tools will bring it back the day an outbound tool is added to the permission manifest. T-102 shows the reviewer correcting the agent. The candidate arrived as spoofing, and the reviewer reclassified it as elevation of privilege because the claims adapter binds each tool call to the market of the claim, so the question is not who the caller is but what the call is permitted to reach. T-101 ends where every accepted threat should end, with controls that have owners and a test that verifies them.
The threat model that fails the pipeline
A threat model that nobody enforces is a document with better formatting. The pipeline turns it into a gate by checking relations that a reviewer reading the diff cannot reliably check. AI Platform and Security, Chapter 17, stated the core rule: every threat names a control, every control names a configuration, and the build fails when a threat has no control or a control has no owner (169, Nordqvist, 2026). This chapter extends it with the rules that make regeneration safe. The gate fails when:
- an accepted or reclassified threat names no control and carries no risk acceptance;
- a threat names a control that the model does not define, or a control has no owner;
- a candidate has no reviewer decision, or a deferral has passed its date;
- a risk acceptance has expired;
- a boundary changed in this pull request and no threat was considered for it.
The last rule is the most valuable, because it catches the failure a reviewer reading only candidates cannot see: a boundary that changed with no candidate at all.
Worked example: The pipeline rule that fails a merge when a threat has no control
The rule below is written in Rego, the policy language of Open Policy Agent (62, Open Policy Agent, n.d.), which is already the language of the platform's policy as code. Its input is threat-model.yaml parsed to JSON, with the date and the boundaries the generator found changed in the pull request added by the CI job. The job evaluates deny and fails when it is not empty. The example is illustrative.
package threatmodel.gate

import rego.v1

# Illustrative. Input: the parsed threat model plus input.today (ISO date)
# and input.changedBoundaries from the generator.

deny contains msg if {
    some t in input.threats
    t.review.decision in {"accepted", "reclassified"}
    count(object.get(t, "controls", [])) == 0
    not t.riskAcceptance
    msg := sprintf("%s: no control and no risk acceptance", [t.id])
}

deny contains msg if {
    some t in input.threats
    some cid in t.controls
    not input.controls[cid]
    msg := sprintf("%s: control %s is not defined", [t.id, cid])
}

deny contains msg if {
    some cid, c in input.controls
    not c.owner
    msg := sprintf("%s: control has no owner", [cid])
}

deny contains msg if {
    some t in input.threats
    not t.review.decision in {"accepted", "reclassified", "rejected", "deferred"}
    msg := sprintf("%s: candidate has no reviewer decision", [t.id])
}

deny contains msg if {
    some t in input.threats
    t.riskAcceptance.expires < input.today
    msg := sprintf("%s: risk acceptance expired on %s", [t.id, t.riskAcceptance.expires])
}

deny contains msg if {
    some b in input.changedBoundaries
    not considered(b)
    msg := sprintf("%s: boundary changed, no threat considered", [b])
}

considered(b) if {
    some t in input.threats
    t.boundary == b
}
The rule does not judge whether a control is adequate. It checks that the relation exists; adequacy is a matter for the reviewer and for the test that follows, because a gate that tried to judge it would be wrong or be trusted too much. Chapter 9 adds the third relation, that a control resolves to a configuration and produces evidence, and classifies each control as verified, declared or failed.
A gate also needs an exit. An urgent change cannot wait two working days when production is down, so the pipeline accepts an exception that names the approver, carries an expiry date and opens a follow-up task. An AI cannot grant it.
From threat model to test
An accepted threat that nothing tests is a belief. The model therefore carries a verifiedBy field that points to an attack case in the continuous red-teaming suite, and a threat without one is declared, not verified, in the sense Chapter 9 gives those words. At Nordvik Region the suite is the AI red-teaming of NR-SEC-002; at Hansa Mutual it is the programme HM-SEC-003 for the claims assistant, the claims-triage agent and the IT-operations agent, with HM-SEC-004 running continuous automated red teaming of the estate (170, Nordqvist, 2026). AI Red Team, Chapters 12 and 13, set out how adversary emulation and the red teaming of AI systems and agents run under written rules of engagement. This chapter supplies what they test.
The attack case is described by its set-up and its expected outcome. For T-101 the case places benign marker content in a test copy of the intake path and checks that the agent's route and the handler's view are unaffected. It never needs the strings an adversary would use, and the book does not print them. The technique identifier on the threat tells the detection-engineering team whether a detection exists for the corresponding behaviour, and a D3FEND countermeasure family can be named where a detection or a control is missing. A finding returns as a pull request, in the spirit of Architecture as Code (Chapter 9C): celebrate the remediation pull request, not just the discovery (167, Nordqvist, 2025).
The loop can fail silently: a trigger path is renamed, the generator is upgraded and stops proposing AI-specific threats, or reviewers stop opening the comments. AI Red Team, Chapter 25, describes security chaos engineering for this purpose (170, Nordqvist, 2026), and the experiment for this chapter injects a condition and not an attack: a pull request in a test repository that adds a boundary, with the hypothesis that a candidate appears within a stated time and that the gate blocks the merge until a named reviewer decides. A failed hypothesis is a finding about the threat-modelling process.
The system-level model also feeds the organisation-level view. AI Threat, Chapter 30, joins the controls an organisation operates to the entries of its AI threat register in a control-to-threat coverage matrix (171, Nordqvist, 2026). The threat models of individual systems are where those controls are shown to be in force.
Practical guide: Introducing generated threat models for one system in eight weeks
Purpose. Replace the workshop-and-document threat model of one system with a model generated from the architecture, reviewed by a named person and enforced by the pipeline, and learn what it costs before extending it.
Roles. The security architect owns the practice and decides. The system owner supplies the knowledge of the business impact. One engineer maintains the pipeline job. The platform team provides the capacity for the generator. For a supplier-run system, the contract owner provides the supplier's evidence. A second reviewer, from the enterprise or AI architecture function, samples decisions.
Steps.
- Week 1. Choose one system with high consequence, an existing architecture model and a nameable owner. Do not start with the most complex.
- Week 2. Run a half-day workshop and answer the four questions. Its output is the baseline against which the generated model is later compared.
- Week 3. Add the security properties to the workspace (zone, data classification, identity, markets) and write down the review triggers.
- Week 4. Fix the schema and the deterministic rules, or adopt an existing tool. Pin the catalogue versions. Check that the workshop's threats load into the schema.
- Week 5. Add the gate in report-only mode and fix the gaps it reports.
- Week 6. Add the AI generator at Level 1 Assisted, writing to pull request comments only. Run it retrospectively on the last ten merged pull requests and compare its candidates with the workshop baseline and with later findings.
- Week 7. Name reviewers in the code-ownership file, set the decision time, brief the reviewers on the soundness criteria and switch the gate to blocking.
- Week 8. Link each accepted threat to an attack case, run the first purple loop and record the decision to extend or stop as an AIDR.
Defaults to adapt. A reviewer decision within two working days; no merge with an undecided candidate; a ten per cent sample of accepted candidates re-reviewed each quarter; catalogue versions reviewed each quarter and whenever a major release is published. An organisation with one reviewer may need five working days and a smaller sample. These values must match its capacity and risk appetite.
Definition of done. Every pull request that touches a trigger path shows a candidate diff, every candidate has a recorded decision by a named reviewer, every accepted threat names controls with owners and an attack case, the gate blocks and has blocked at least once for a real gap, and the baseline comparison is recorded.
Across the usage modes and autonomy levels
The mode of the system under review decides what the threat model must show, because it decides whose identity the AI uses and who judges each action (169, Nordqvist, 2026). The mode of the tool used for the review is a separate matter and is covered in Chapter 12.
Across the usage modes
| Mode | Dominant threat to model | Typical boundary | Who judges |
|---|---|---|---|
| Mode 0 Ambient AI | Automatic scoring or actions in licensed software that the organisation cannot inspect | Supplier boundary; recorded as a contractual property | The supplier's model |
| Mode 1 Conversational assistants | A person misled by a plausible answer, or data pasted into an unapproved tool | Person to approved tool | The person |
| Mode 2 Embedded workplace assistants | Injected content in documents and mail that the assistant reads with the user's access | Content source to assistant context | The person, with delegated access |
| Mode 3 Agentic work tools | An agent acting with an engineer's credentials between instruction and review | Agent to repository, shell and credentials | A person, after the agent acts |
| Mode 4 Built AI applications | Third-party or resident-written content steering the system; model and retrieval supply chain | Retrieval ingest, prompt assembly, output into the system of record | Named reviewers and owners |
| Mode 5 Autonomous production agents | A manipulated machine insider with identity and permissions of its own | Agent to tools and core systems | Policy outside the agent, and its operators |
For Modes 1 and 2 the model concentrates on the person and the approvals the person can give. For Modes 3 and 5 it concentrates on the identity the AI holds and on every edge that identity opens.
Across the autonomy levels
| Level | Use in threat modelling |
|---|---|
| Level 0 Advisory | The architect asks for candidate threats or an explanation and decides what to use |
| Level 1 Assisted | The generator drafts the candidate diff; a named reviewer decides each candidate; the default for this chapter |
| Level 2 Supervised | The pipeline writes accepted items to the model after the reviewer approves each change |
| Level 3 Bounded | Reversible housekeeping only, such as refreshing links or re-running generation on a trigger, with the owner informed |
| Level 4 Autonomous | Not used: no AI accepts a threat, a risk or an exception |
Observable, expected and speculation
Three statements about the future of this practice carry their labels. It is observable that threat models are kept as code and generated from rules in open-source tools (178, OWASP, n.d.) (180, Schneider, n.d.), and that AI-proposed candidate threats with a human reviewer are in use in early adopters; the evidence for the second is practitioner reporting and the design in the earlier volumes, not systematic study. It is expected that regeneration on change spreads as architecture models become code, because the regulatory duties above ask for continuous risk management and because the marginal cost of a regenerated model falls with the model's quality. It is speculation that AI-proposed threat models will reach the quality of expert workshops without human review. Evidence on the quality of AI-proposed threats compared with workshops is limited, the book treats it as an open question, and nothing in this chapter depends on the answer.
Nordvik Region and Hansa Mutual
Nordvik Region starts from a position of strength in one place: the threat model of the citizen-service assistant is already code (AI Red Team, Chapter 10). The Region extends the practice to the benefits-triage system, recorded as AIDR-0510. The difficulty is that TriageSoft, the supplier under tender NR-2026-117, owns much of the design, so the workspace shows the system as a container with contractual properties. The threat model records, for each threat the supplier's part of the system raises, the contractual control, the evidence the Region receives under the contract and a named Region-side owner who verifies it. The Region models in depth the boundaries it controls as deployer: the intake of applications, the claims ranker's inputs and the output into the caseworker's queue. For a high-risk system the model also shows, entry by entry, that the attack classes named in Article 15(5) of the AI Act were considered (1, European Union, 2024). The generator runs as a Mode 3 tool on open-weight models on the Region's reserved capacity, within the mandate MND-NR-01. The single security architect decides every candidate, which makes the architect a single point of failure and removes the second reviewer, so the AI architect samples a tenth of the decisions each quarter. Accepted models are classified before storage because public-access rules would otherwise make them requestable.
Hansa Mutual generates the model from its Structurizr workspace for every system that touches the claims-triage agent: the claims adapter, the service-centre integrations, the claims assistant and the intake path. The threat-modeller agent of the review team proposes candidates under MND-HM-01 and a named architect decides: the AI domain architect for the agent itself, and the architect embedded at the Polish service centre for the market-bound controls. The fortnightly review board no longer sits in the path of these changes; it sees contested items only. Hansa links each threat to the control catalogue that Chapter 9 completes and to the control-to-threat coverage matrix CCM-HM-2027-01 of AI Threat, Chapter 30 (171, Nordqvist, 2026). The decision to make generated threat models a gate for every system that touches the agent is recorded as AIDR-0564. Because the review agents read pull requests and can show who wrote what, their rollout in each entity waits for works-council consultation in Germany and the Netherlands and union consultation in Sweden. The two differ in breadth and not in method: Nordvik models a few systems in depth because its reviewers are few, and Hansa needs generation because no person can read every pull request.
Summary
Threat modelling changes from a workshop that produces a document to a practice in which the model is generated from the architecture repository, regenerated when a boundary moves and enforced by the pipeline. This is Shift 1, from documents to code: the threat model is a versioned artefact in the vocabulary of STRIDE, attack trees, MITRE ATT&CK, MITRE ATLAS and D3FEND, and it fails the build when a threat has no control, a control has no owner, a candidate has no decision or a boundary changed without being considered. The workshop remains for what the code cannot hold.
It is also Shift 3, from periodic to continuous, at machine speed. Regeneration on every change that alters the threat surface gives a defensible answer to the supervisor's question whether each significant change was considered, and the loop itself is verified by an experiment that injects a boundary and checks that the process responds. Accepted threats become attack cases in the red-team suite, and their results return as pull requests.
Shift 4, from sole author to conductor of an AI team, appears as the threat-modeller agent. The AI adds breadth, speed, translation between vocabularies and a first draft of the difference between two versions. It has no access to the risk appetite, the unmodelled flows or whether a control works, and it produces plausible text whether or not a threat is grounded. It works at Level 1 Assisted: it proposes, soundness is defined in advance, a named reviewer decides each candidate against its provenance, review quality is measured and no AI accepts a threat, a risk or an exception. For AI and agentic systems, natural language is an instruction channel and the mitigation sits outside the model, so the threat model's most useful entry for an agent is the record of which legs of the lethal trifecta it holds.
The model sets out what must hold; Chapter 7 turns it into boundaries. It treats the boundary as the architect's main product and shows how zero trust, policy decision points, default-deny egress and containment profiles keep an agent within its limits whatever anyone intends.
Sources
- European Parliament and Council of the European Union. Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act). Official Journal of the European Union, 12 July 2024. (1, European Union, 2024)
- European Parliament and Council of the European Union. Directive (EU) 2022/2555 on measures for a high common level of cybersecurity across the Union (NIS 2 Directive). (6, European Union, 2022)
- European Parliament and Council of the European Union. Regulation (EU) 2022/2554 on digital operational resilience for the financial sector (DORA). (9, European Union, 2022)
- Vassilev, A., Oprea, A., Fordyce, A., Anderson, H., Davies, X. & Hamin, M. (2025). Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations. NIST AI 100-2 E2025. (30, Vassilev et al., 2025)
- OWASP Foundation. OWASP Top 10 for Large Language Model Applications, 2025 edition. (44, OWASP, 2025)
- OWASP Foundation (2025). OWASP Top 10 for Agentic Applications for 2026. (45, OWASP, 2025)
- MITRE Corporation. MITRE ATT&CK: Adversarial Tactics, Techniques, and Common Knowledge. (46, MITRE, n.d.)
- MITRE Corporation. MITRE ATLAS: Adversarial Threat Landscape for Artificial-Intelligence Systems. (47, MITRE, n.d.)
- MITRE Corporation. MITRE D3FEND: A knowledge graph of cybersecurity countermeasures. (48, MITRE, n.d.)
- Threat Modeling Manifesto Working Group. Threat Modeling Manifesto. 2020. (49, Threat Modeling Manifesto Working Group, 2020)
- Microsoft Learn. Threats – Microsoft Threat Modeling Tool (STRIDE model). (50, Microsoft, 2017)
- Structurizr. Structurizr DSL language reference. (60, Structurizr, n.d.)
- Open Policy Agent Contributors. Open Policy Agent Documentation. Cloud Native Computing Foundation. (62, Open Policy Agent, n.d.)
- Shostack, A. (2014). Threat Modeling: Designing for Security. Wiley. (71, Shostack, 2014)
- Parasuraman, R. & Manzey, D. H. (2010). Complacency and Bias in Human Use of Automation: An Attentional Integration. (107, Parasuraman & Manzey, 2010)
- Microsoft AI Red Team (2025). Taxonomy of Failure Modes in Agentic AI Systems. (117, Microsoft, 2025)
- Greshake, K., Abdelnabi, S., Mishra, S., Endres, C., Holz, T. & Fritz, M. (2023). Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection. (123, Greshake et al., 2023)
- Willison, S. (2025). The lethal trifecta for AI agents: private data, untrusted content, and external communication. (124, Willison, 2025)
- Reddy, P. & Gujral, A. S. (2025). EchoLeak: The First Real-World Zero-Click Prompt Injection Exploit in a Production LLM System. (125, Reddy & Gujral, 2025)
- Milanta, M. & Beurer-Kellner, L. (2025). GitHub MCP Exploited: Accessing private repositories via MCP. (126, Milanta & Beurer-Kellner, 2025)
- Nordqvist, G. (2025). Architecture as Code. (167, Nordqvist, 2025)
- Nordqvist, G. (2026). AI Platform and Security: Building and Securing AI Platforms in European Enterprises and Public Authorities. (169, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Red Team: AI as an Active Part of Cyber Defence in European Enterprises and Public Authorities. (170, Nordqvist, 2026)
- Nordqvist, G. (2026). AI Threat: Are the Dystopias Coming True? Evidence, Risk and Response for European Enterprises and Public Authorities. (171, Nordqvist, 2026)
- OWASP Foundation. OWASP pytm: a Pythonic framework for threat modelling. (178, OWASP, n.d.)
- Schneier, B. (1999). Attack Trees: Modeling Security Threats. Dr. Dobb's Journal. (179, Schneier, 1999)
- Schneider, C. Threagile: Agile Threat Modeling Toolkit. (180, Schneider, n.d.)
- Huang, K. (2025). Agentic AI Threat Modeling Framework: MAESTRO. Cloud Security Alliance. (181, Huang, 2025)
- GitHub. About code owners. GitHub Docs. (174, GitHub, n.d.)